UnifAPI vs Firecrawl / Tavily: page readers vs. public-data Skills

Updated
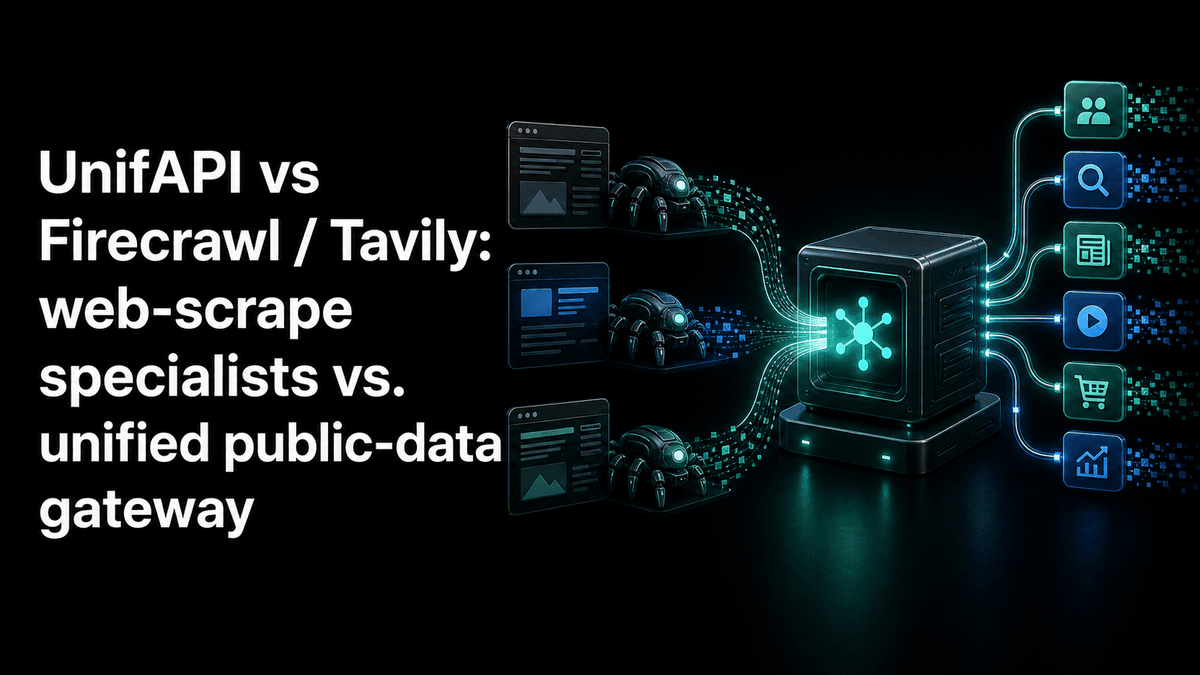
Firecrawl and Tavily read web pages for agents; UnifAPI gives agents public social records and task Skills like KOL pricing and social listening.
In short: This article separates page-reading and answer-search tools from UnifAPI's platform-native social records, so teams can combine the right tools instead of forcing one layer to do everything.
Firecrawl and Tavily are URL-to-markdown specialists: hand them a link, get back clean, LLM-ready text, often with structured extraction on top. They're the cleanest answer in the agent ecosystem for "read this page for me." UnifAPI starts from a different live surface: public social records plus Skills that ask an agent to produce a task result.
Where Firecrawl and Tavily win
Both vendors focus on one thing and do it well: turn an arbitrary URL into something an LLM can read. Firecrawl emphasizes structured extraction ("give me the product name and price from this page as JSON"), site crawling ("map every page under this domain"), and a clean markdown output. Tavily emphasizes RAG-friendly search-and-summarize on top of the open web, with an answer-engine flavor.
If your agent's job is to read pages and your inputs are URLs, both are excellent. The DX is tight, the markdown is genuinely clean, and the structured-extraction shortcut beats writing your own selectors.
Why agents end up needing more
Most agents start with "read this page" and end up needing "find the pages worth reading." That second half is where scrape vendors hand off to either a search API or a social-platform API. "Summarize what TikTok creators are saying" doesn't start with a URL — it starts with a query against TikTok. "Find the top Reddit threads about X" doesn't start with a URL either.
Once the agent needs to discover URLs as well as read them, you're suddenly running two vendor integrations: a scrape specialist plus a search or social API. That's the boundary where UnifAPI takes over.
What UnifAPI bundles in
UnifAPI is one MCP and HTTP surface across social (TikTok, LinkedIn, Instagram, YouTube, Twitter/X, Threads, and Reddit). Same envelope, same pagination, same rate sheet.
For an agent that starts with creator discovery, KOL pricing, social listening, or competitor monitoring, UnifAPI keeps the public-social integration count at one. Page-reading tools can still sit beside it when the workflow reaches a URL that needs extraction.
Pricing comparison
Page readers usually price around pages, crawls, or extraction calls. UnifAPI prices public-data work with $0.001 credits and published operation minimums, with the model execution handled by the agent product you already use. The durable question is not which pricing page is cheaper this week; it is whether the workflow needs pages or platform-native records.
How to decide
Pick Firecrawl if your inputs are mostly URLs, structured extraction is your core need, and your team is happy operating two or three specialist vendors for the discovery half. Pick Tavily if you specifically want answer-engine semantics out of the box.
Pick UnifAPI if your agent needs public social inputs, task-specific Skills, and predictable record pricing. Pair it with a page reader when the task genuinely needs arbitrary URL extraction.
Browse Skills at unifapi.com/skills, inspect the live catalog at unifapi.com/apis, see pricing at unifapi.com/pricing, or wire the MCP server in three minutes at unifapi.com/mcp.
What to read next
UnifAPI vs Exa - continues the search and discovery comparison cluster.
Minimum viable agent stack - shows where page readers and public-data APIs fit together.
Build a Reddit research agent - shows a workflow that uses records before pages.